By combining our deep clinical domain expertise with the Databricks Data Intelligence Platform, we enable you to move from manual, reactive data processing to a continuous, AI-ready unified clinical data ecosystem that accelerates insight generation across the entire R&D portfolio Built on Delta Lake and medallion architecture, this foundation keeps every downstream dataset reliable, versioned, and analysis-ready. Together, we help R&D leaders move from fragmented, study-specific workflows to a unified single source of clinical truth.
Clinical R&D has outgrown the tools it was built on. Data is fragmented across EDC, CTMS, safety, labs and eTMF; AI ambitions stall in pilots that never reach production; and every analytical shortcut has to answer to a regulator. Databricks was built for exactly this kind of problem, and paired with clinical domain expertise, it becomes a foundation R&D organizations can actually build on.
One platform, not a stack of disconnected tools.
Most clinical data problems begin with fragmentation, a different system for every function, none speaking to the others. Databricks unifies data engineering, analytics, and AI on a single Lakehouse, so trial, lab, safety and operational data live in one governed place. For R&D, that enables a single source of truth.
Built in governance.
In regulated environments like life sciences, Unity Catalog makes access control, end-to-end lineage, and audit trails native to the platform, the foundation for GxP-aligned, inspection-ready analytics, rather than a compliance layer retrofitted after the fact.
Open and interoperable by design.
Built on open formats like Delta Lake and Iceberg, Databricks avoids the lock-in that makes clinical data estates so hard to evolve. Data can be standardized to CDISC and SDTM, shared securely across sponsors, CROs and sites, and remain portable as your ecosystem changes.
Built to scale from one study to the whole portfolio.
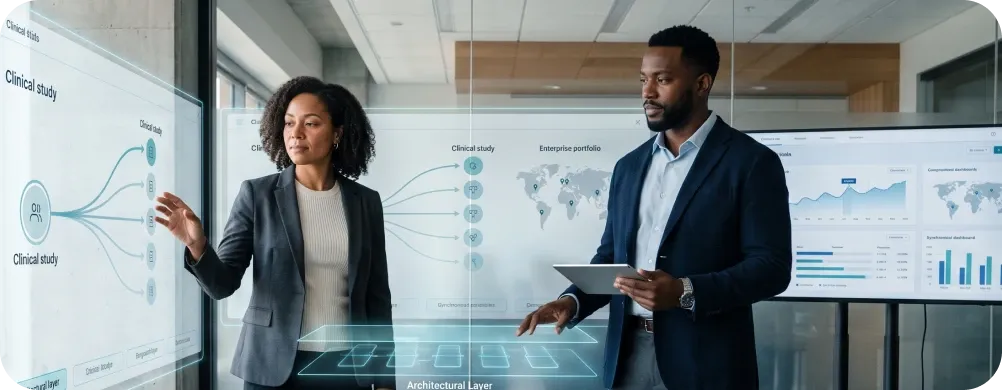
Cloud-native and elastic, the platform handles a single study or an enterprise R&D portfolio on the same architecture, so the foundation you build for one trial becomes the operating model for all of them.
The platform is necessary. The partner makes it real.
A capable platform doesn't guarantee a successful outcome, implementations succeed or stall on the operating model, the validation approach, and whether the people building it understand clinical operations, not just the technology. That's where i2e comes in.
As a Databricks consulting and systems integrator partner, we bring a certified team delivering across the full Databricks platform, data engineering and governance with Unity Catalog, Databricks SQL analytics, machine learning with MLflow, and GenAI and agentic AI with Agent Bricks, built to match the regulated, data-intensive demands of clinical development.
Unifies EDC, CTMS, safety, labs, and eTMF into one governed source of truth, so every team works from the same data instead of manual handoffs.
Moves legacy warehouses and SAS environments to the Databricks Lakehouse through validated, sequenced migrations that minimize disruption to ongoing studies and keep workloads audit-ready.
Builds automated pipelines that harmonize EDC, CTMS, safety, labs, eTMF, and RBQM data into governed, submission-grade datasets on Delta Lake.
Uses Unity Catalog to make the Databricks environment auditable by design, with unified access control, full data lineage, and a complete audit trail.
Turns governed clinical data into real-time risk detection, plain-English answers, and AI that moves from pilot to production.
Unifies risk, safety, and site signals scattered across four or more tools into one real-time view, surfacing risk before it escalates rather than after a Central Monitor catches it manually.
Layers AI/BI Genie, Agent Bricks, and i2e's ORION on governed data so teams can ask plain-English questions, from site risk to portfolio resourcing, without writing SQL.
68% of AI pilots in life sciences never reach production. We build the governed path from experiment to validated deployment, with agents your platform team can actually sign off on.
The Clinical Data Readiness Assessment is available as a complimentary engagement for qualifying organizations.
Phase 1:
Clinical data readiness assessment (weeks 1–2)
We map your current data estate, systems landscape, EDC, CTMS, RTSM, safety, labs, eTMF, and readiness gaps on Databricks. You leave knowing exactly where you stand.
Phase 2:
Integration blueprint & architecture (weeks 3–6)
We design your connected clinical data architecture on Databricks: Unity Catalog governance model, medallion architecture, CDISC-aligned, GxP-compliant, and cloud-native from day one.
Phase 3:
Ecosystem build & intelligence layer (months 2–4)
We integrate your systems, automate pipelines, and activate the AI/analytics layer, Genie, Agent Bricks, ORION with your teams embedded throughout, deploying apps via Databricks Apps or Posit so non-technical users can work inside the platform directly.
Phase 4:
Scale, adoption & value realization (Month 4+)
We measure outcomes, drive adoption across functions, and build the operating model, ongoing monitoring, cost and performance tuning, and expansion into new GenAI and agentic use cases, that sustains transformation at scale.
Since there was a vision to move completely to the new data lake being built on Databricks – the team was also looking to move beyond SAS programming
Centralized, Scalable Data Access with Unity Catalog Using Databricks' Unity Catalog, our admin granted secure, governed access to the client's data lake